Research
Fundamental interpretability research to understand and intentionally design advanced AI systems
Filter By
Fundamental Research
Neural Networks Are Already Clean
Applied Research
Training and Deploying Production Cyber Monitors on Kimi K3
Applied Research
Better biosecurity monitors for AI agents via protein embeddings
Applied Research
Models know when they’re reward hacking — and we can catch them at scale
Fundamental Research
Forking Fast: Efficiently Estimating Uncertainty Dynamics in Text Generation
Fundamental Research
Uncovering Neural Geometry in Vision Models With Block-Sparse Featurizers
Fundamental Research
Meandering on Manifolds: The Neural Geometry of Stories Over Time
Applied Research
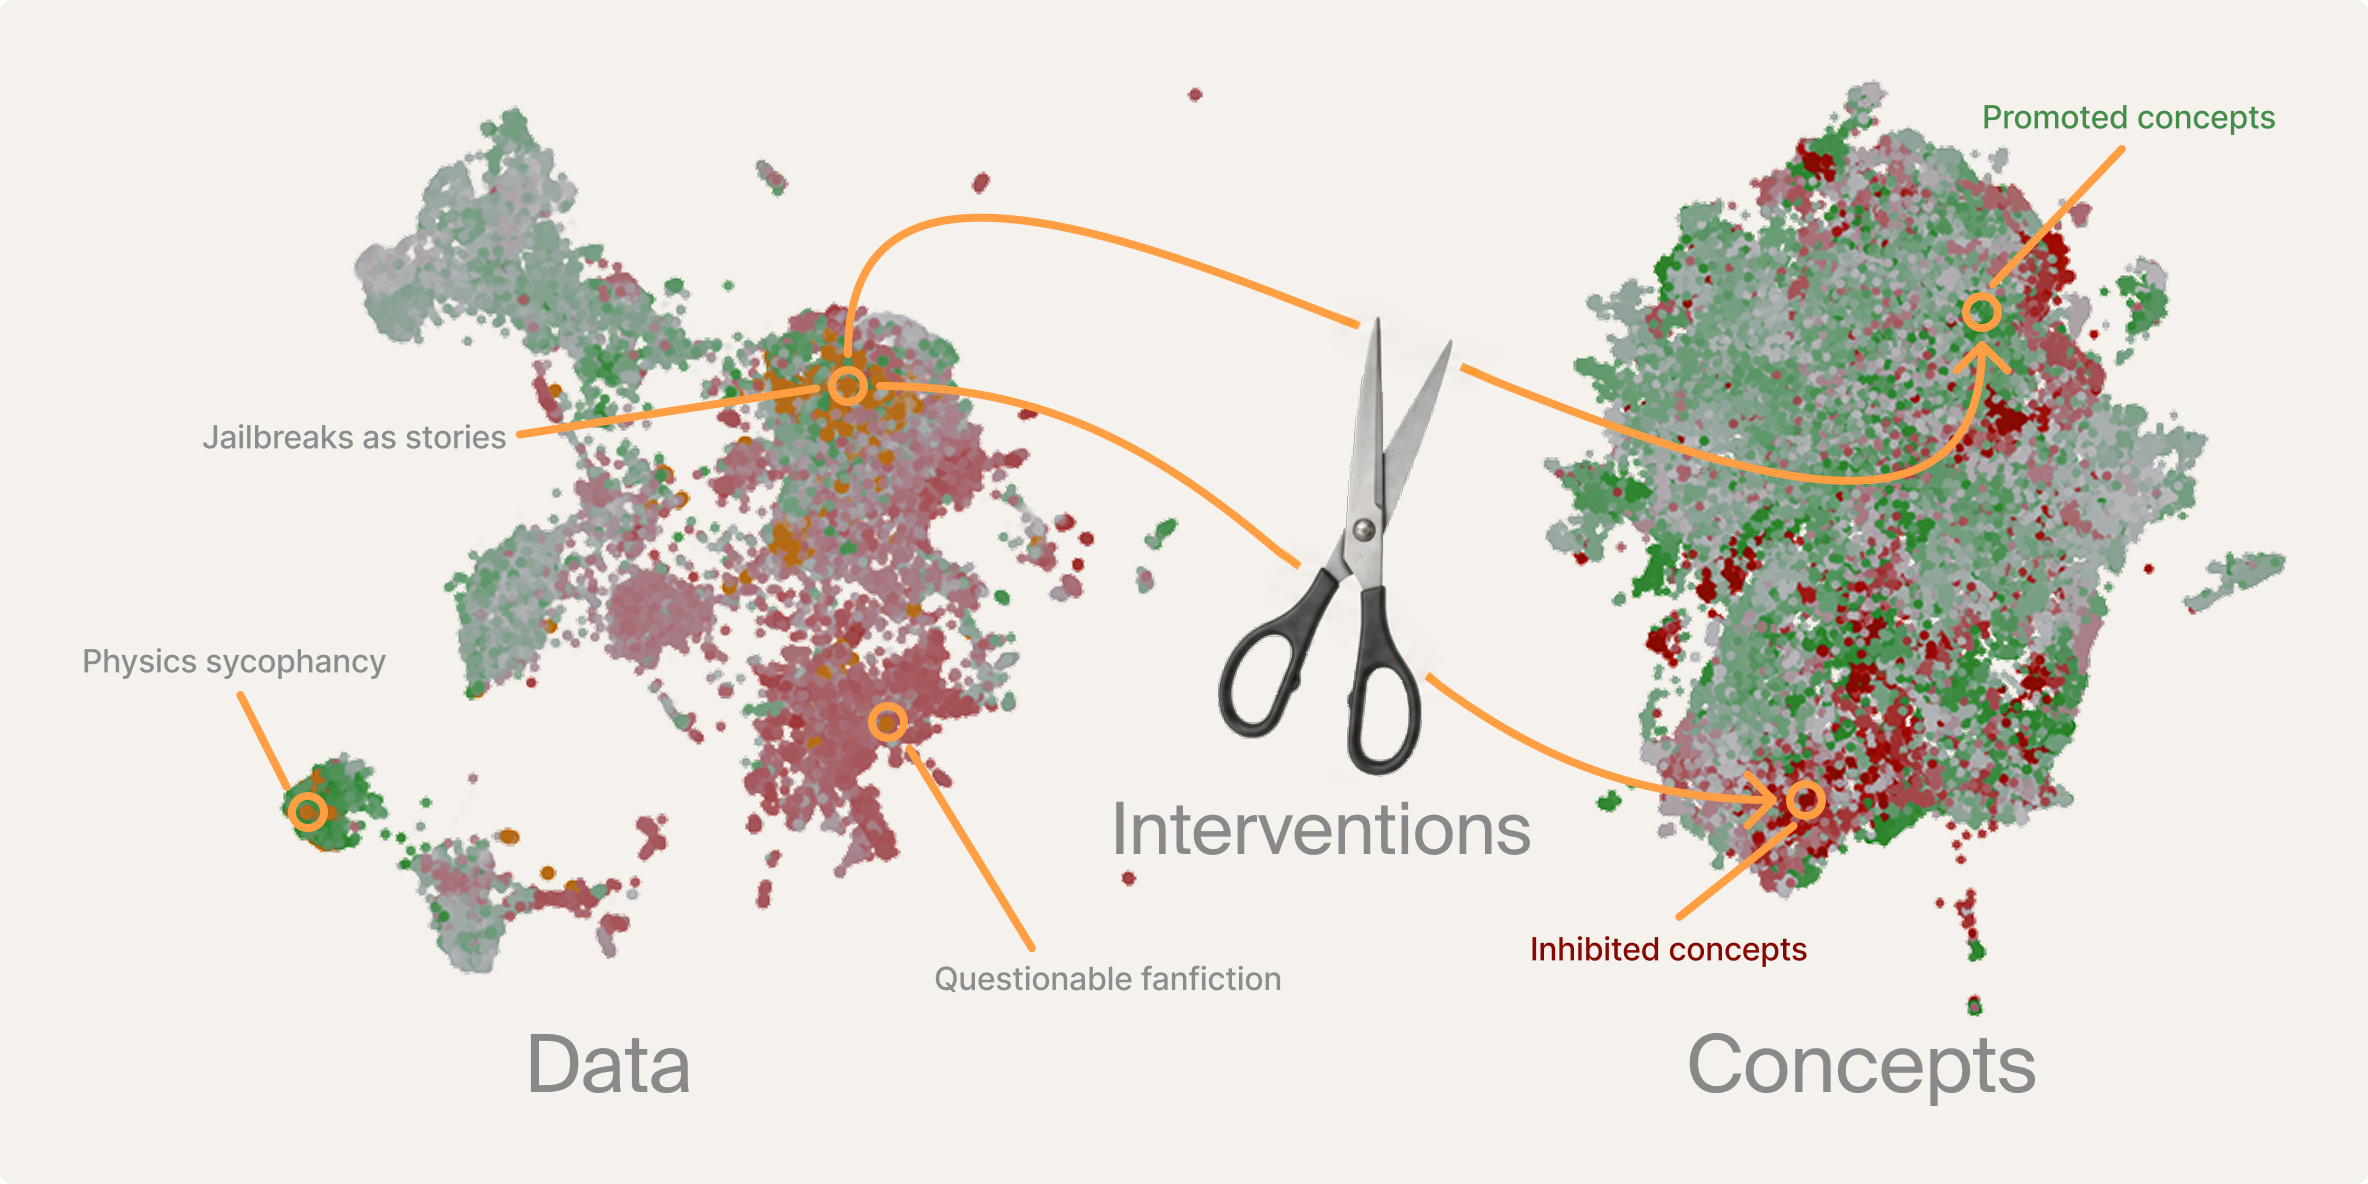
Predictive Data Debugging: Reveal and Shape What Your Model Learns, Before You Train
Link postApplied Research
Logits as a new monitor for evaluation awareness
Fundamental ResearchLink post
Why Larger Models Learn More: Effects of Capacity, Interference, and Rare-Task Retention
Fundamental Research
Can SAEs Capture Neural Geometry?
Fundamental Research
A Geometric Calculator Inside a Neural Network
Link post
Predicting Rare LLM Failures with 30× Fewer Rollouts
Fundamental Research
Steering Along Manifolds to Control Neural Networks
Fundamental Research
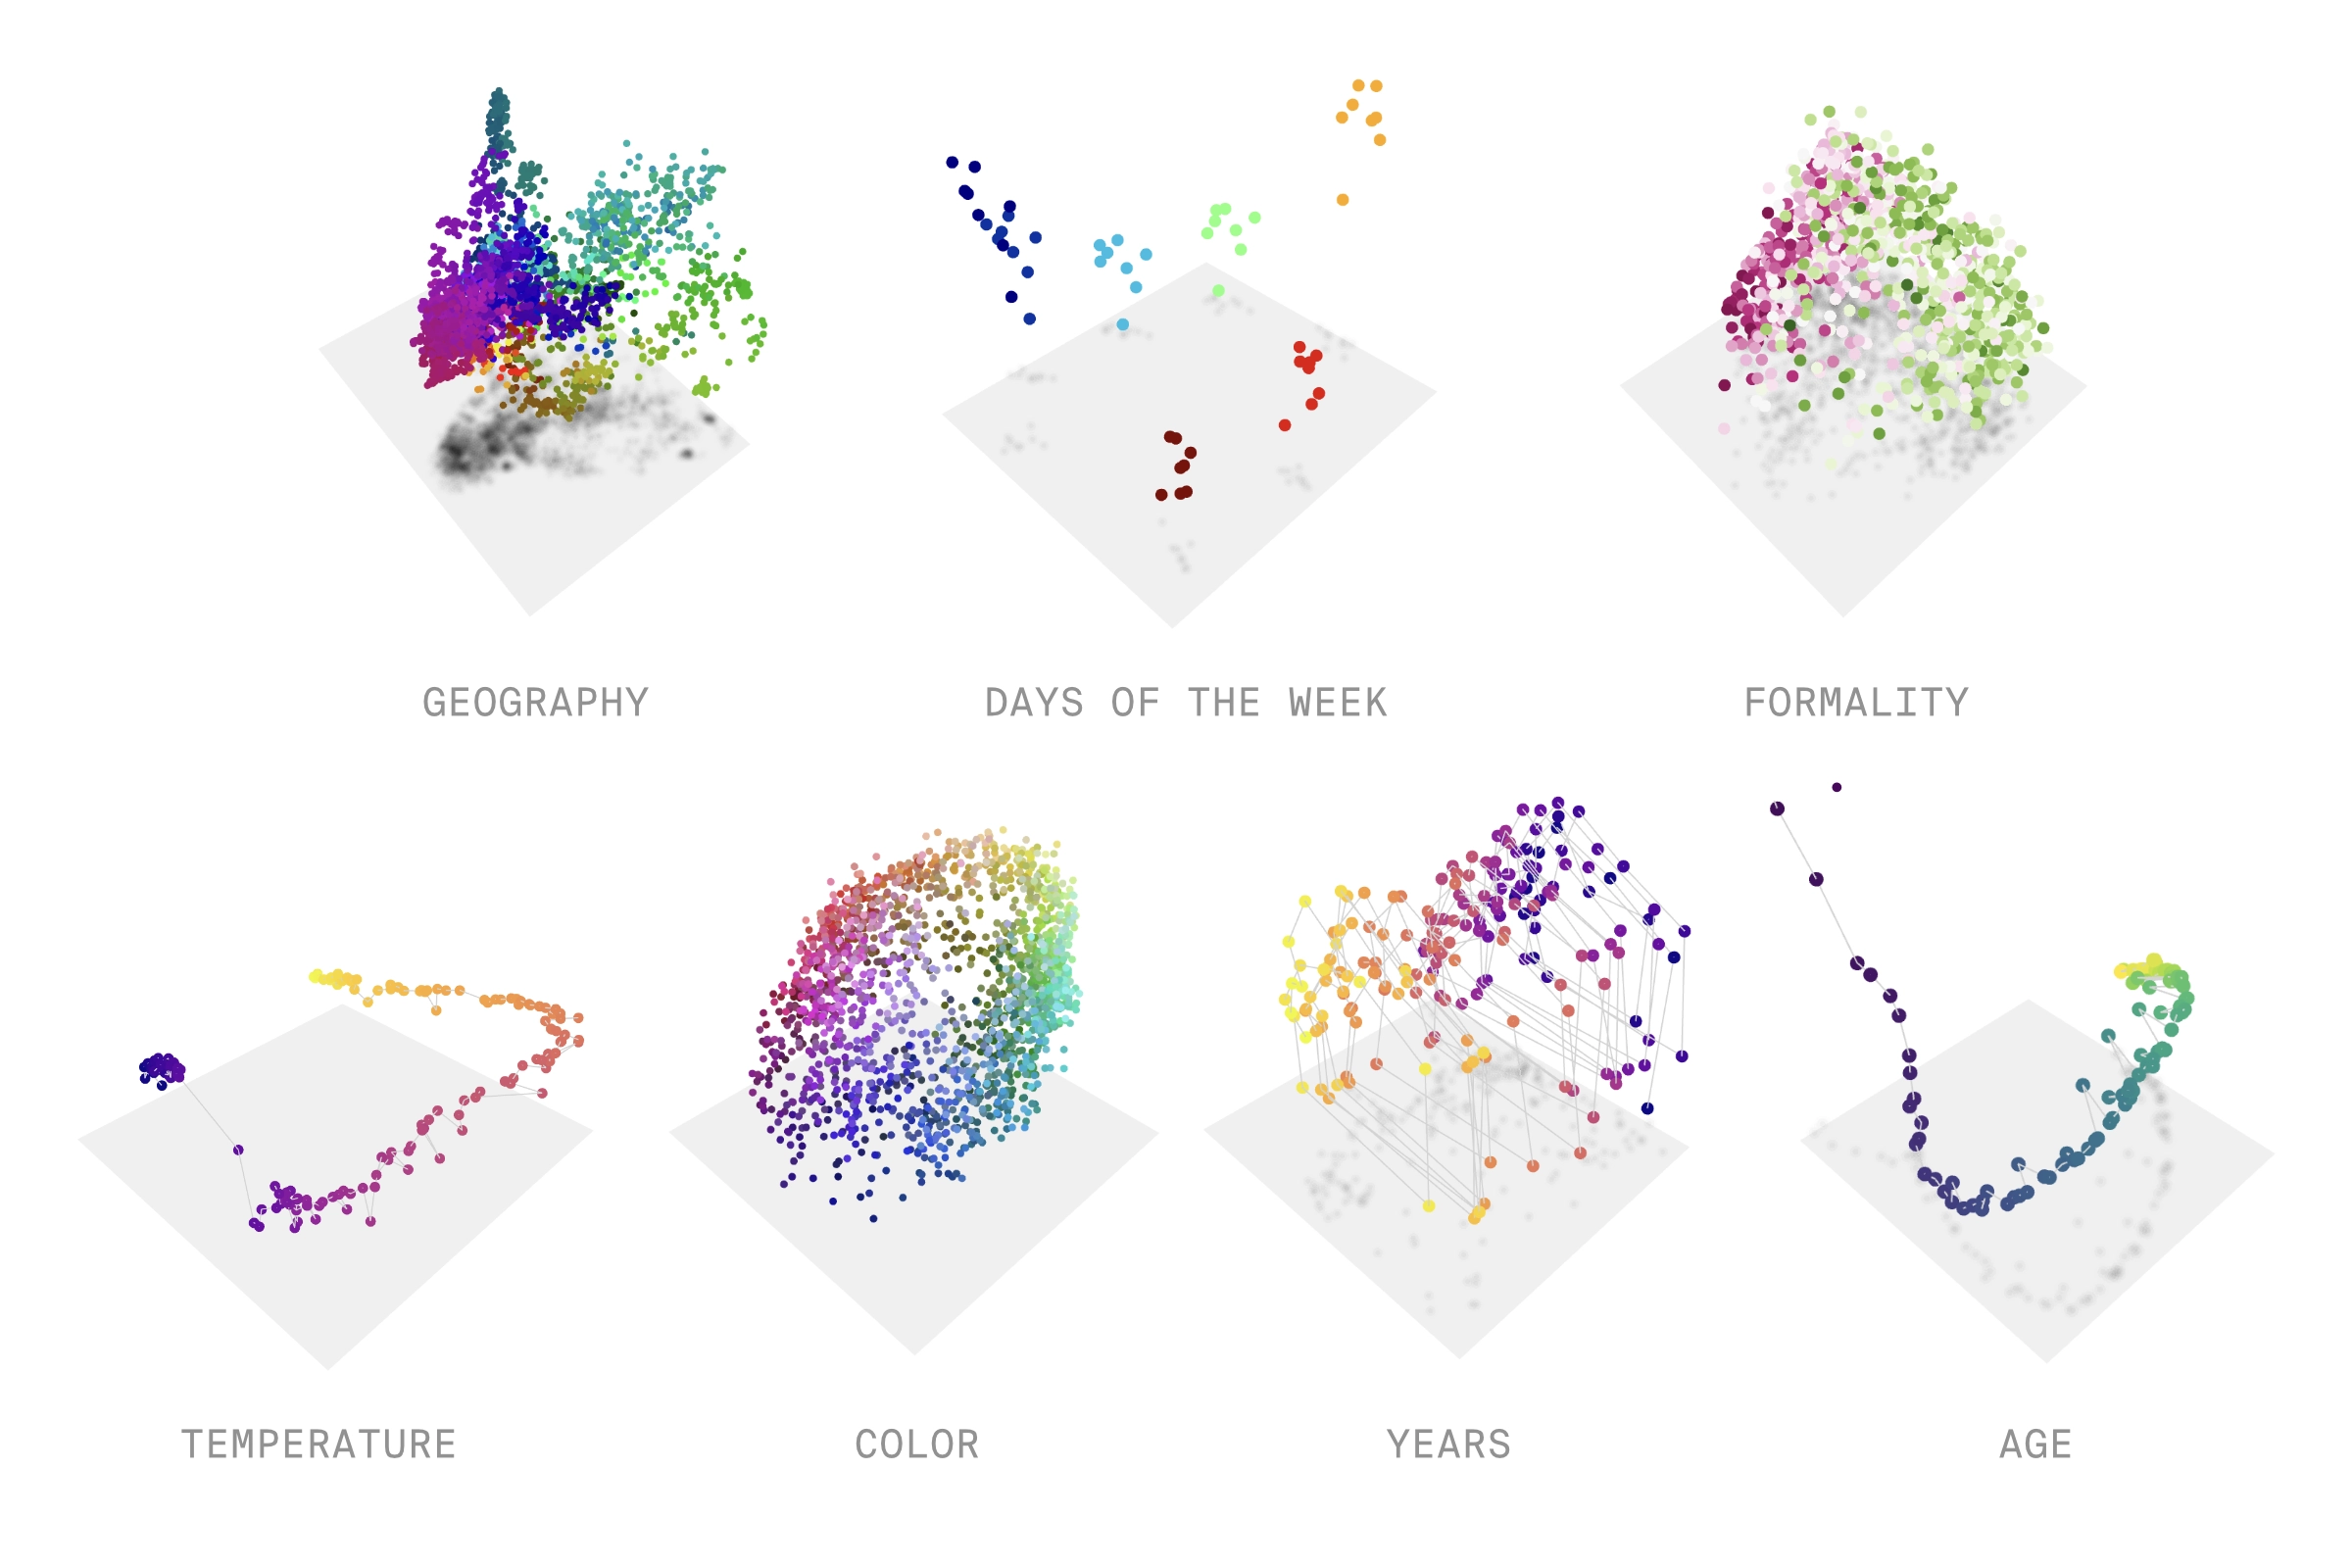
The World Inside Neural Networks
Fundamental Research
Paper Summary: Interpreting Language Model Parameters
Fundamental Research
Interpreting Language Model Parameters
Applied Research
Verbalized Eval Awareness Inflates Measured Safety
Applied Research
Probe-Based Data Attribution: Surfacing and Mitigating Undesirable Behaviors in LLM Post-Training
Applied Research
Explaining 4.2 million genetic variants with state-of-the-art, interpretable predictions
Fundamental Research
Covariance-based Sequence Pooling
Applied Research
Using Self-Correcting Search to Accelerate Materials Discovery
Applied Research
Reasoning Theater: Probing for Performative Chain-of-Thought
Fundamental Research
Features as Rewards: Using Interpretability to Reduce Hallucinations
Applied Research
Using Interpretability to Identify a Novel Class of Alzheimer's Biomarkers
Fundamental Research
Understanding Memorization via Loss Curvature
Fundamental ResearchLink post
Priors in Time: Missing Inductive Biases for Language Model Interpretability
Fundamental ResearchLink post
Belief Dynamics Reveal the Dual Nature of In-Context Learning and Activation Steering
Applied Research
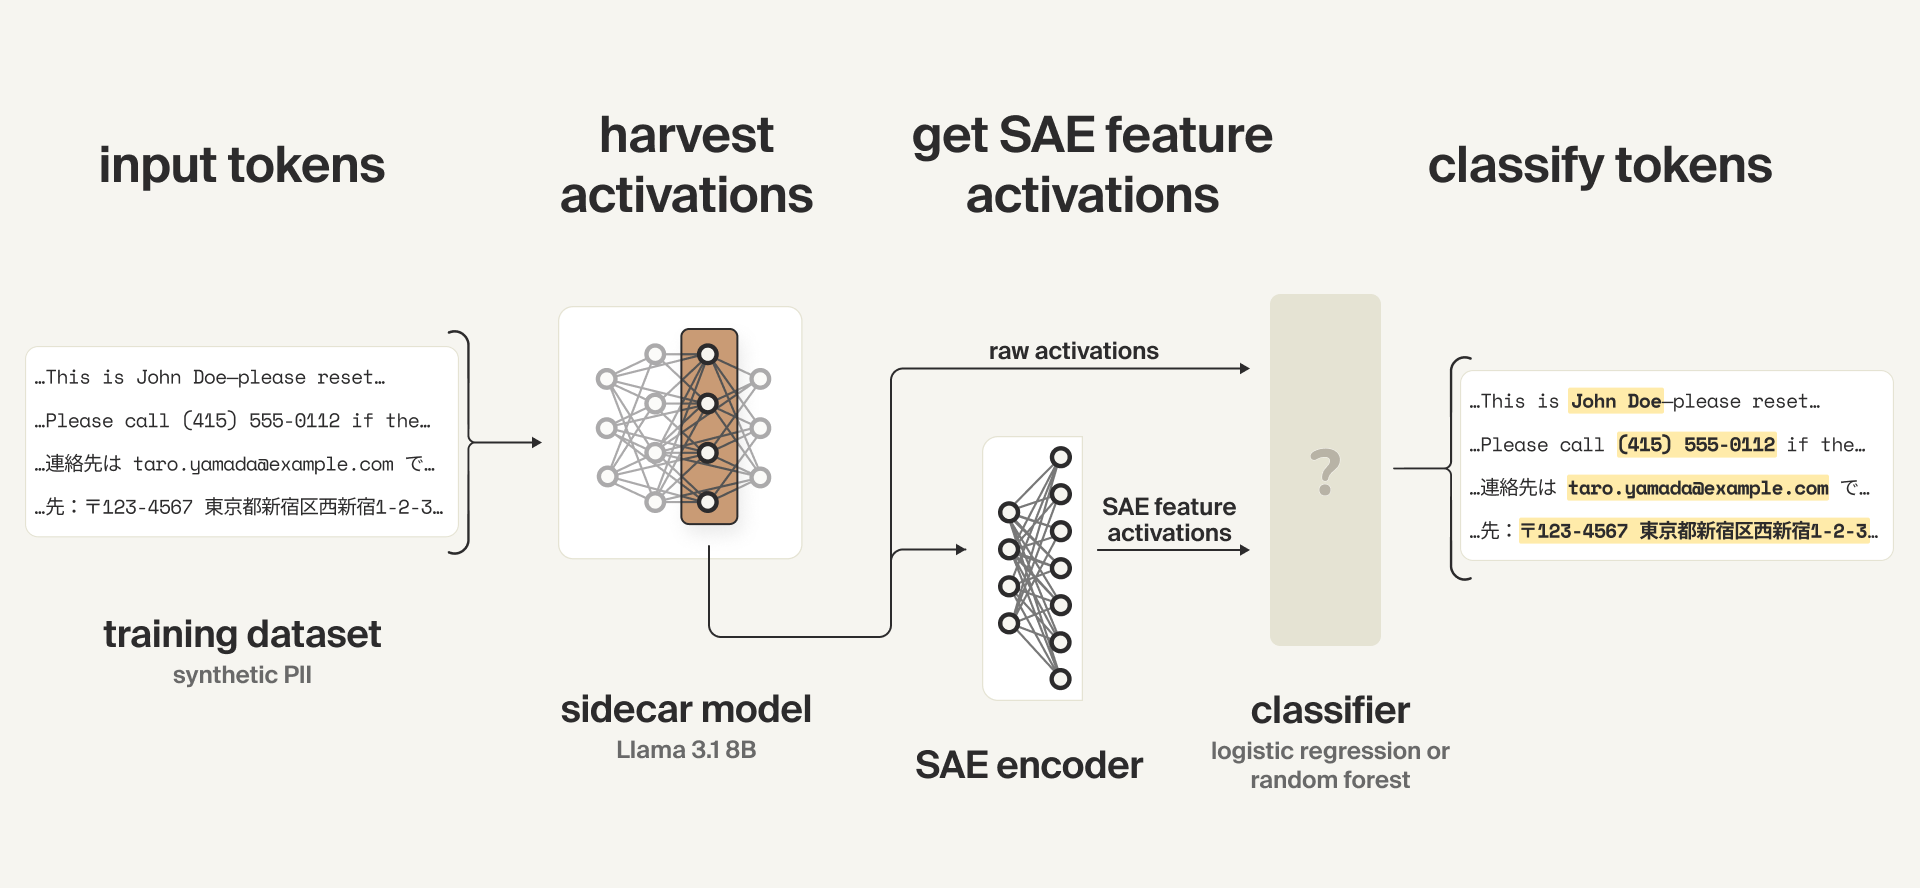
Deploying Interpretability to Production with Rakuten: SAE Probes for PII Detection
Fundamental ResearchLink post
Mixing Mechanisms: How Language Models Retrieve Bound Entities In-Context
Fundamental ResearchLink post
Understanding Sparse Autoencoder Scaling in the Presence of Feature Manifolds
Applied Research
Finding the Tree of Life in Evo 2
Fundamental ResearchLink post
Adversarial Examples Are Not Bugs, They Are Superposition
Applied Research
Discovering Undesired Rare Behaviors via Model Diff Amplification
Fundamental ResearchLink post
The Circuits Research Landscape: Results and Perspectives
Fundamental Research
Towards Scalable Parameter Decomposition
Fundamental Research
Replicating Circuit Tracing for a Simple Known Mechanism
Applied Research
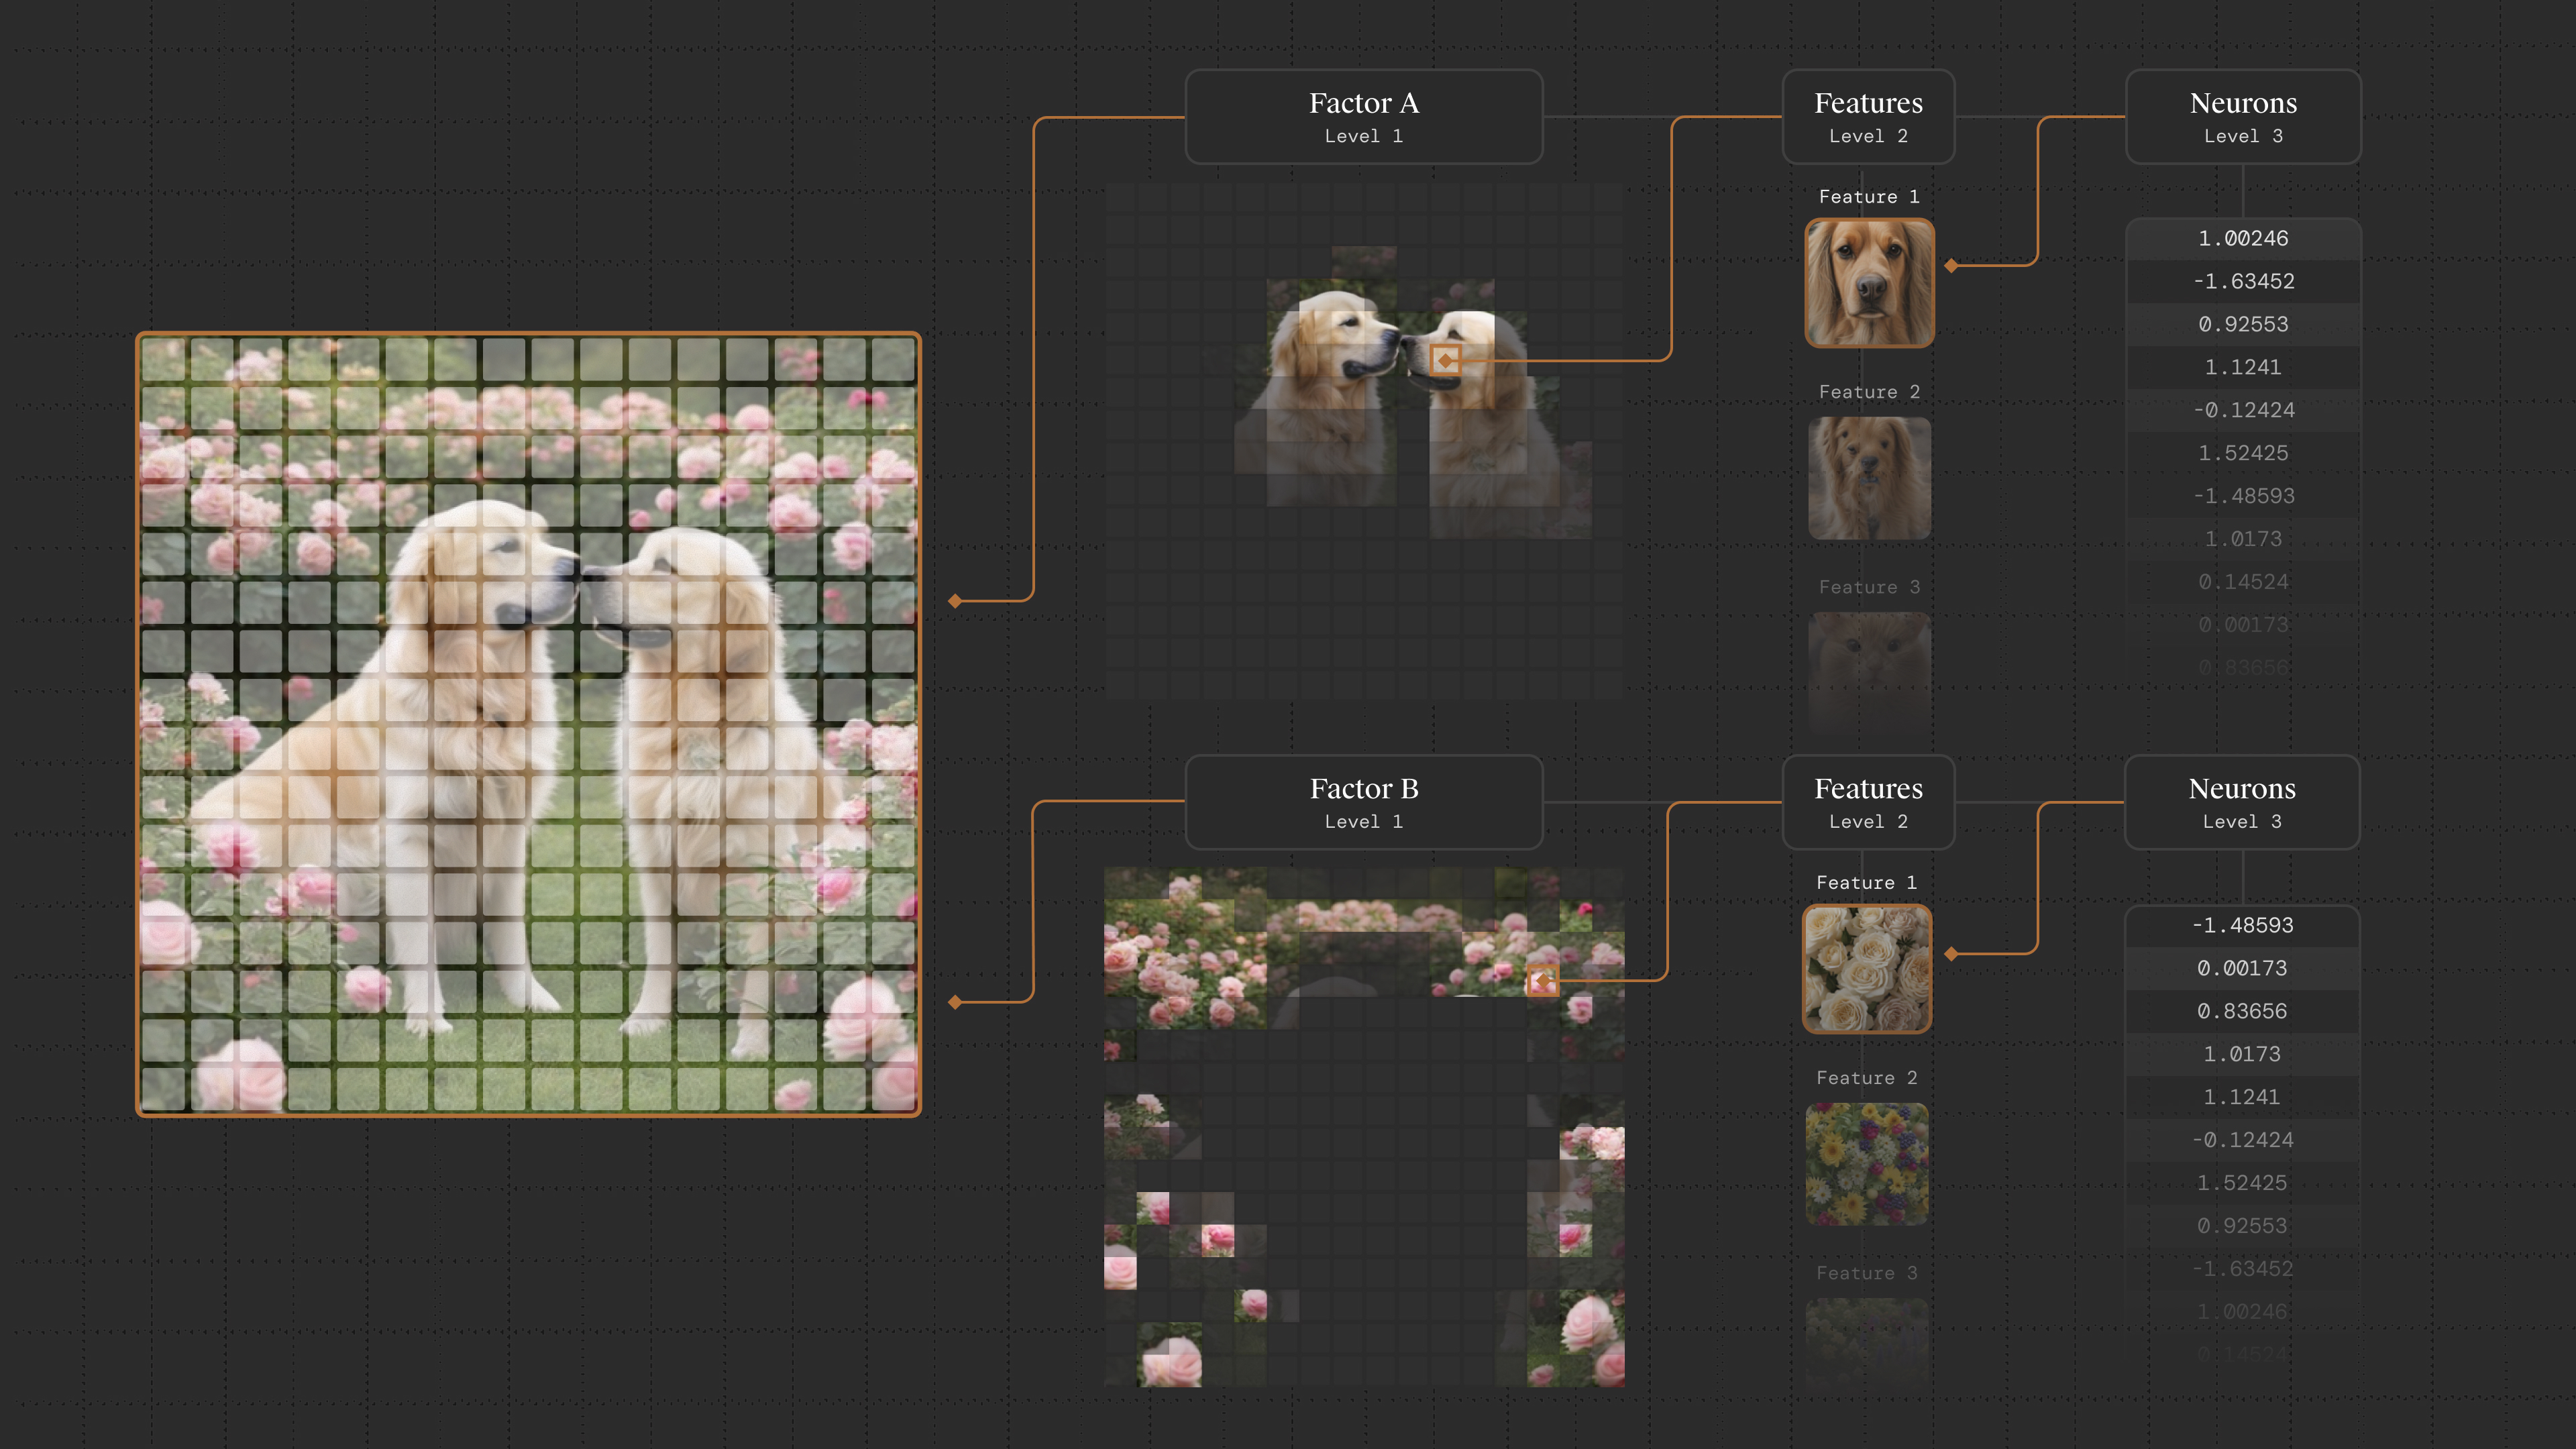
Painting With Concepts Using Diffusion Model Latents
Fundamental Research
Under the Hood of a Reasoning Model
Applied Research
Interpreting Evo 2: Arc Institute's Next-Generation Genomic Foundation Model
Fundamental ResearchLink post
Open Problems in Mechanistic Interpretability
Applied Research
Mapping the Latent Space of Llama 3.3 70B
Applied Research
Understanding and Steering Llama 3 with Sparse Autoencoders
Interpretability for all types of AI models
 LLMs
 Life Sciences
Talk to our team
Interested in partnering with Goodfire?